On this page
During a healthcare backend migration to Kotlin and Spring Boot, I investigated slow APIs and unexpectedly high SQL Server CPU usage. APM, database monitoring and JVM profiling helped narrow the wider investigation. One database finding needed a much smaller experiment: a lookup had an index matching its conditions, but the ORM query was not using the access path I expected.
The existing hospital schemas used CHAR and VARCHAR for several indexed identifiers. I observed that string parameters from the application were being sent as Unicode. That gave me a concrete difference to investigate: the application and database agreed on the value, but not on its SQL type.
The difficult part was preserving three requirements together: efficient lookups on existing indexes, Unicode support where hospitals needed it, and compatibility with databases whose column definitions differed. This article covers the execution-plan investigation and the binding decision. The second article follows the read failure that decision exposed into Hibernate and the JDBC driver.
Reduce the problem to one lookup
Some application queries joined more than ten tables. Starting there would leave too many possible explanations: join order, predicates, cardinality estimates and the way the ORM generated SQL. I instead used a lookup on a two-column key: a hospital identifier stored as CHAR(8) and a customer key stored as VARCHAR(20).
I kept the values and predicates the same and changed only whether the string literals had the N prefix. The identifiers and values below are neutral substitutes; the types and comparison preserve the experiment. This is a pair of literal queries used to investigate the application behavior, not a capture of a prepared statement’s parameter declarations.
SELECT *
FROM customer_record
WHERE hospital_key = '00000000'
  AND customer_key = '#1000001'
OPTION (RECOMPILE);

SELECT *
FROM customer_record
WHERE hospital_key = N'00000000'
  AND customer_key = N'#1000001'
OPTION (RECOMPILE);
'value' is an ordinary character literal; N'value' is a Unicode character literal. Both queries ask for the same row. The difference is the type entering the comparison.
I also suspected the optimizer’s plan choice, including the possibility of misleading statistics. OPTION (RECOMPILE) let me compare freshly compiled plans instead of reusing an existing cached plan. It does not ignore statistics, update them or rule out a statistics problem. That limits what this part of the experiment establishes. SQL Server’s query-hint documentation describes the distinction.
Read the access path, not just the presence of an index
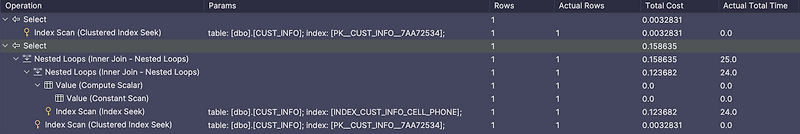
The first plan used the expected clustered key lookup. The Unicode version used a nonclustered phone-number index, followed by access to the clustered key and additional nested-loop work. It was surprising because the query’s conditions were on the hospital and customer keys, not the phone-number field.
The nonclustered index did not cover the full SELECT * result. The additional clustered access retrieved row data that was unavailable from that index alone. A plan containing an index seek can therefore still be a poor access path for the intended lookup; the operator name is not enough to judge the work.
The useful observation was the difference between the two plans. The screenshot includes seek operations. It does not demonstrate that every Unicode parameter causes a full table scan, and its optimizer costs should not be read as measured milliseconds or a production speedup.
Remove the alternative index, then change the column types
I made the next changes on a copied table. First, I removed the phone-number index and repeated the Unicode lookup. That prevented the optimizer from taking the alternative path seen in the first comparison.

The resulting plan still contained nested-loop and scalar operations around clustered-key access. At that point I suspected work introduced by the type mismatch. The Inner Join label alone was not enough to establish exactly which expressions SQL Server converted or how many rows it processed. That would require the predicate and conversion expressions from the full plan, together with runtime row counts and reads. I treated the operator tree as a clue rather than proof of a whole-table conversion.
Next, I changed both indexed lookup columns in the copied table to NVARCHAR and repeated both literal queries.

Both forms now used the intended access path. That made the type mismatch a much stronger explanation than the original observation alone.
| Comparison | What I changed | What the result supported |
|---|---|---|
| Ordinary versus Unicode literals | Literal type, with values and predicates held constant | The type entering the comparison affected the selected plan. |
| Unicode lookup without the alternative index | Available indexes on a copied table | The unexpected phone-number path could be removed, but the remaining plan still needed explanation. |
Both lookup columns changed to NVARCHAR | Physical types on the copied table | Aligning the types restored the intended path for both literal forms in this experiment. |
Changing an indexed column also involves index maintenance and can affect statistics. These were practical diagnostic experiments, not a controlled benchmark isolating every optimizer input. Together with the application’s Unicode binding and SQL Server’s conversion rules, they justified investigating the type boundary. They did not establish the behavior of every ORM query.
Explain the difference through type precedence
SQL Server gives NVARCHAR higher precedence than VARCHAR and CHAR. When expressions with different types are compared, the lower-precedence type is converted toward the higher-precedence type where an implicit conversion is supported. Microsoft’s precedence table explains the direction.
For a VARCHAR column compared with an NVARCHAR value, that direction can put conversion on the column expression. The index is organized around the stored column values; a converted comparison may make the intended seek less useful or require a different access strategy. Whether it does so depends on the collation, predicate and optimizer behavior.
In the opposite direction, an ordinary string value compared with an NVARCHAR column can be converted on the value side. That explains why changing the copied columns to NVARCHAR was consistent with the plans I observed. It is a mechanism to check in the plan, not a rule that all mixed-type comparisons have the same outcome.
The next question was what the application actually sent. A Java or Kotlin String does not itself determine whether SQL Server receives VARCHAR or NVARCHAR. Hibernate’s mapping selects JDBC operations, and the driver’s configuration affects ordinary string binding. Looking only at the SQL text with ? placeholders misses that part of the query’s input.
Compare three places to make the types agree
There were three approaches worth considering.
| Approach | Why I considered it | What made it difficult |
|---|---|---|
Convert indexed character columns to NVARCHAR | The copied-table experiment restored the intended access path. | It changes hospital-owned schemas, requires handling dependent indexes and creates compatibility work for existing clients. |
Keep Unicode binding as the default and bind selected indexed attributes as CHAR/VARCHAR | It preserves a Unicode default while matching the existing lookup columns. | I found selective binding difficult to apply reliably through this Spring/Hibernate/JDBC stack. A mapping declaration had to reach the actual parameter setter. |
| Use ordinary string binding by default and keep selected attributes nationalized | It matches the prevalent legacy columns and gives explicit Unicode attributes their own path. | The shared mapping also controls result extraction, while physical column types differ across hospitals. |
I initially preferred the second approach. The implemented direction was the third: change the default binding and retain explicit Unicode mappings for the attributes that needed them. The investigation records that difficulty with selective binding; it does not establish that every supported custom-type approach was impossible.
Why a successful schema experiment was not a deployment plan
Converting the copied table was useful evidence. Applying that change across hospital databases was a different decision. Existing software also used those tables, including native queries outside my application. I would have had to coordinate schema changes, dependent-index recreation and client compatibility.
Storage was another consideration. For ASCII-like identifiers, moving from a single-byte encoding to Unicode storage can enlarge keys and reduce how many fit on a page. The exact effect depends on the encoding, values and index layout. VARCHAR is not universally one byte per character, and NVARCHAR is not universally two bytes per Unicode character; multibyte code pages, UTF-8 collations and UTF-16 surrogate pairs matter. CHAR/VARCHAR storage and NCHAR/NVARCHAR storage define those limits.
Those were deployment and capacity considerations, not measured storage or I/O regressions from this incident. Keeping the existing schemas avoided making them prerequisites for the application fix.
Change the ordinary binding, preserve the Unicode requirement
The datasource configuration included this connection property:
sendStringParametersAsUnicode=falseThe JDBC URL property has no set prefix. setSendStringParametersAsUnicode(false) is the corresponding Java setter form.
The following Kotlin excerpt is adapted from the datasource construction. Names are illustrative and unrelated connection options are omitted:
fun buildLookupJdbcUrl(host: String, port: Int, database: String): String =
    "jdbc:sqlserver://$host:$port;databaseName=$database;" +
        "sendStringParametersAsUnicode=false"
The setting changes ordinary character-parameter transmission. It does not force every string through a non-Unicode path: national methods such as setNString always send Unicode. For selected attributes I retained Hibernate’s @Nationalized mapping so those values could use that explicit path. The JDBC property reference documents both behaviors and the risk of character loss when a non-national path cannot represent a value.
This distinction matters operationally. A lookup key can need ordinary binding to match a legacy index, while another attribute still needs Unicode storage. A connection-wide switch alone cannot describe both requirements.
The next failure was on the way back from the database
Saving the nationalized attributes preserved the Unicode characters needed by those databases. Reading the same mapped attribute from some other hospitals failed:
The conversion from varchar to NCHAR is unsupported.The application mapping was shared, but one hospital could have an NVARCHAR column where another still had VARCHAR. Hibernate used the national getter for the mapped attribute in either case. That exposed a separate result-conversion rule inside the driver.
I followed that failure from Hibernate’s extractor through ResultSet.getNString() to the driver’s conversion map, then implemented a startup compatibility workaround. The two fixes address different directions: the connection setting affects parameters going to SQL Server; the workaround affects the driver’s acceptance of values coming back. The library investigation includes the code path, rejected alternatives and the risks of the workaround.
Results and the checks the fix requires
The overall binding and compatibility fix produced the historical result of 20% lower database CPU usage and 80% shorter execution time for queries that had missed their intended indexes. These are the production results I reported for the complete fix. They are not measurements derived from the screenshots, an improvement across every query, or the isolated effect of the getter workaround.
For another deployment, I would validate the same two directions explicitly:
| Boundary | Evidence needed |
|---|---|
| Application to database | Actual JDBC setter and parameter type, physical column type and collation, and the resulting execution plan. |
| Query execution | Logical reads, CPU and elapsed time under comparable conditions, alongside seek predicates and row counts. |
| Database to application | Read/write round trips for supported column types, representative Korean and other non-ASCII values, empty strings and nulls. |
| Startup workaround | Confirmation that the intended conversion entries changed before the affected reads begin. |
The useful progression was from a slow request to a small comparison, then from that comparison to the parameter type and the deployment boundary I could change. Restoring an index path was only part of the solution: the application still had to preserve the intended characters across the different hospital schemas.